Monitoring Your Minelaying Flutter: Hashrate, Latency, And Logs That Matter
A minelaying farm earns money only when its machines are working, and the difference between a sound fleet and a struggling one is often nonvisual without good monitoring. Pool-boards show your unquestioned hashrate, but they seldom explain why it dropped. A proxy waiter sitting in the midsection of the can fill in that missing detail.
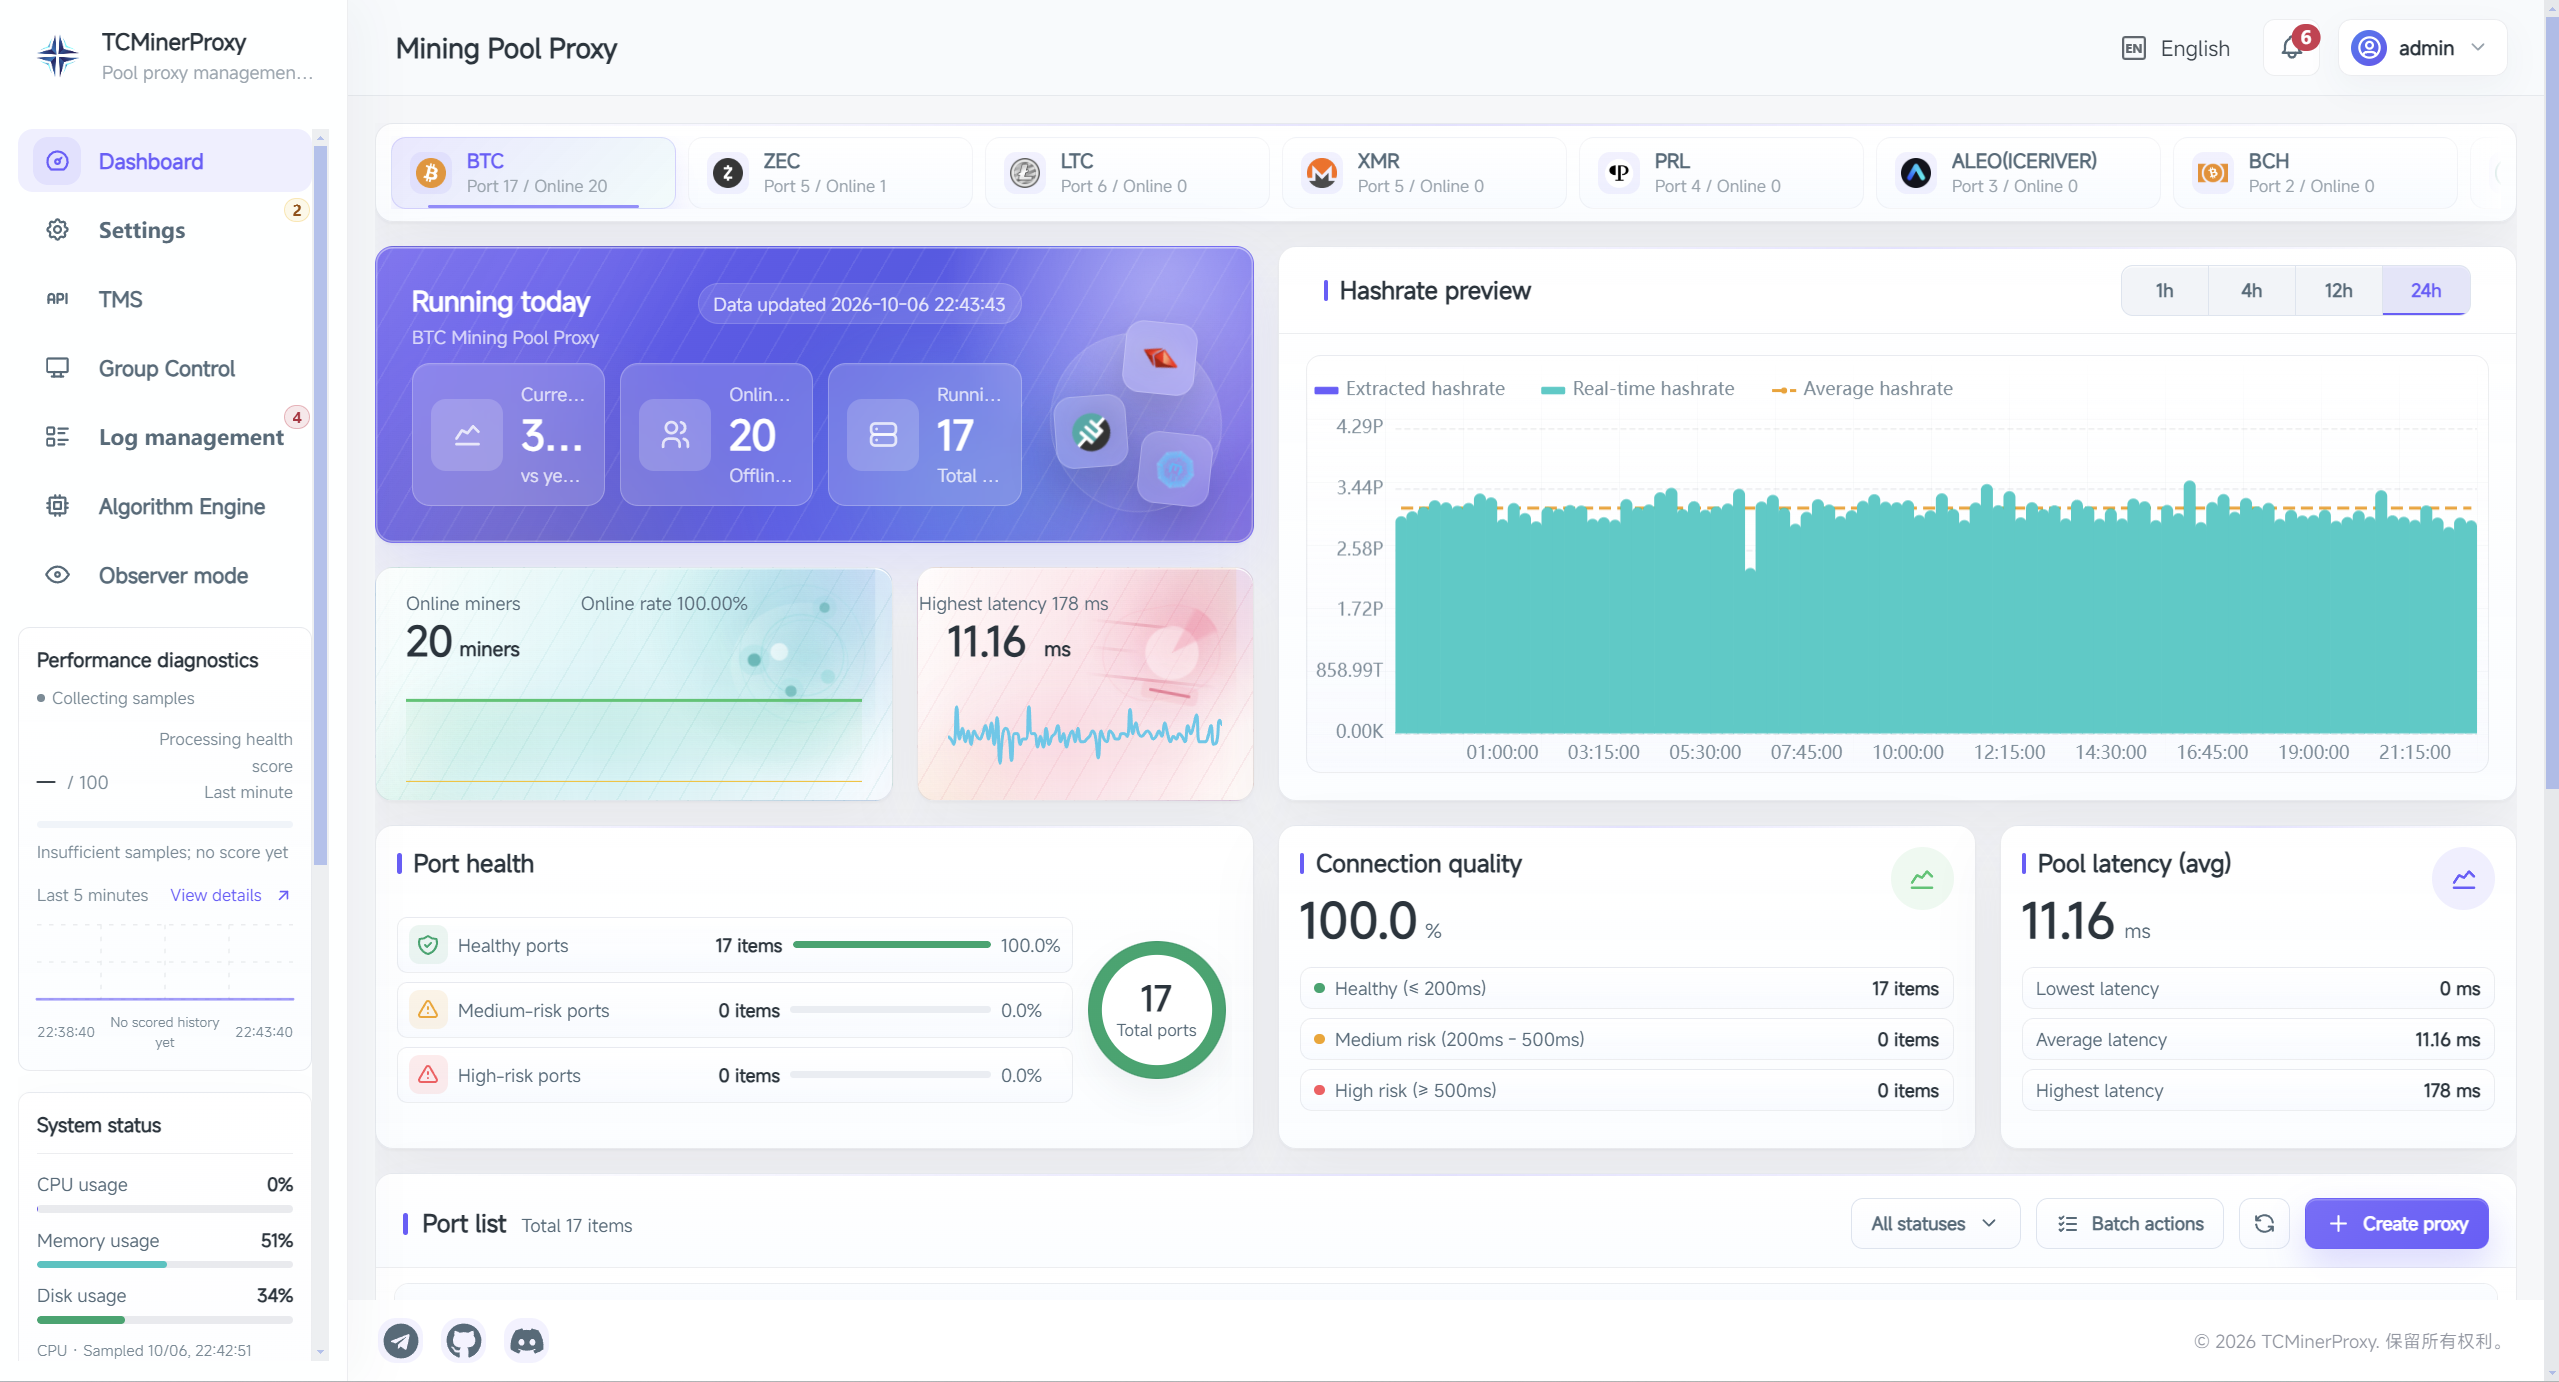
Begin with hashrate, the most self-explanatory metric. Track it at several levels: total flit, per site, per group, and per worker. A drop in add together hashrate tells you something is wrongfulness, but a partitioning tells you where. If one site dips while others hold becalm, you probably have a local web or major power issue. If a unity worker declines, the itself needs attention. Platforms like TC minerproxy let out live hashrate and device entropy on the waiter, which makes this kind of -down possible.
Next, see latency. High or reactive latency between miners and the pool leads to moth-eaten shares, which means wasted work. If you road traffic through a placeholder, measure the at each hop: mineworker to placeholder, and procurator to pool. Sudden spikes can direct to congested links, overladen servers, or a pool endpoint having inconvenience oneself. Having this data lets you react chop-chop, for instance by switching to a closer or fitter upriver turn to.
Connection counts and states deserve tending too. A flutter that on the spur of the moment shows fewer connections than expected may be suffering from superpowe outages, swop failures, or assay-mark problems. Likewise, a empale in reconnects often signals reactive network . Seeing entry and outflowing connections in one view makes these patterns easier to catch.
Logs are your diagnostic tape. Runtime logs disconnects, rejected shares, conformation changes, and errors. Reviewing them regularly helps you empathise patterns rather than sporadic events. When something goes wrongfulness at 3 a.m., a timestamped log is often the only way to restore what happened. Keep logs long enough to equate flow behavior against sooner weeks, and back up contour so you can restitute a known-good put forward rapidly.
On-site resources matter to as well. If you use a local anesthetic client like TMS, monitoring ports, link position, dealings, CPU, and retention helps insure the collecting level itself is not the bottleneck. A starving waiter can look like a pool problem when it is really a resource problem.
Finally, make monitoring actionable. Decide what counts as abnormal, such as a percentage drop in hashrate or a rotational latency threshold, and set up a procedure for checking it. Whether you rely on alerts or a review, the target is . Good monitoring does not keep every failure, but it shortens the time between a trouble coming into court and a fix being applied, and across a vauntingly dart, those preserved hours add up to real tax income.